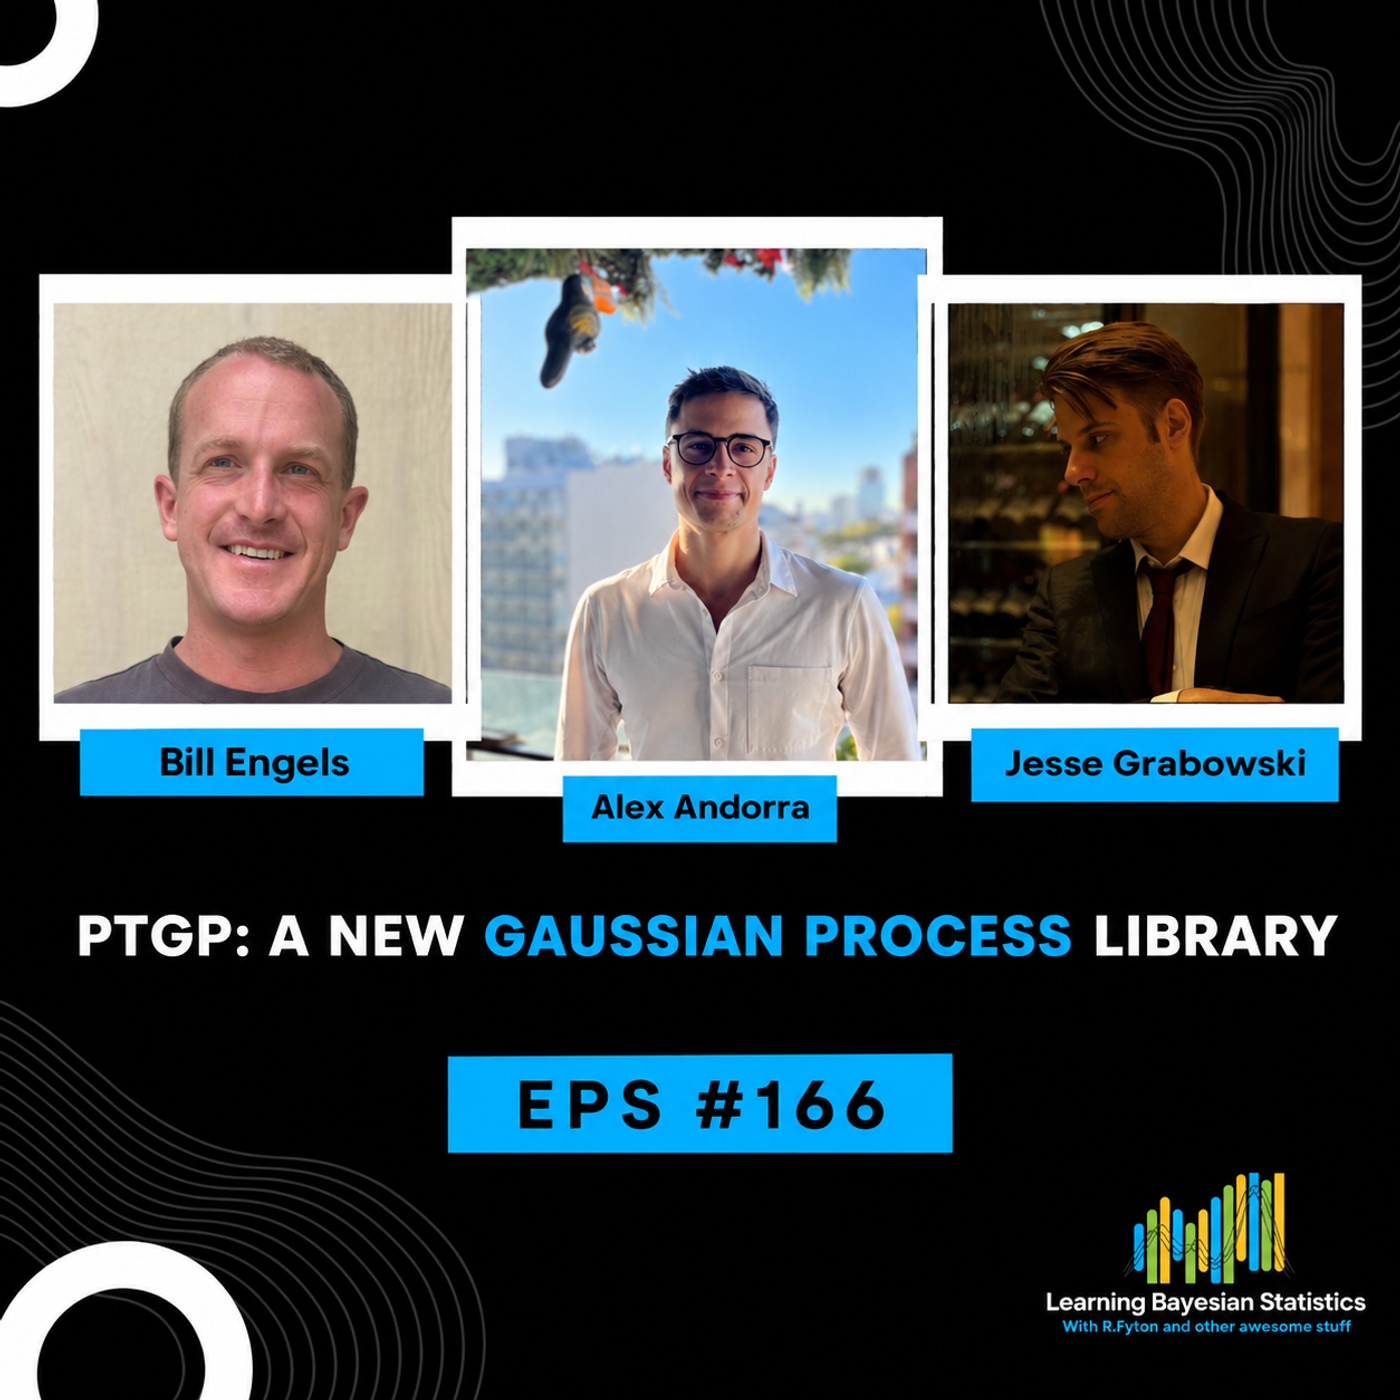
#166 PTGP: A New Gaussian Process Library, with Bill Engels & Jesse Grabowski
Support & Resources → Support the show on Patreon → Bayesian Modeling Course (first 2 lessons free) Our theme music is « Good Bayesian », by Baba Brinkman (feat MC Lars and Mega Ran). Check out his awesome work! Takeaways : Q: What is PTGP and why did Bill and Jesse build it? A: PTGP is a new Gaussian process library built on PyTensor and PyMC, aimed squarely at practitioners rather than researchers assembling their own GP methods from papers. Bill Engels, who wrote PyMC's original GP submodule during a Google Summer of Code, built it because most GP libraries implement one method well but give little guidance on when to use it or how to fix it when it breaks. PTGP is opinionated by design: it picks battle-tested algorithms, tells you which one fits your data size, and ships the debugging knowledge alongside the code. Q: Why are Gaussian processes described as sitting at the intersection of statistics and machine learning? A: A Gaussian process starts from a simple idea: things that are close in the input space should be close in the output space, and the kernel function defines exactly what "close" means for your problem. That makes GPs look like machine learning (let the data speak through a flexible function) while staying fully interpretable once you've chosen a kernel, since observing data collapses the process into an ordinary multivariate normal. Full takeaways here ! Chapters : 05:51 Where do Gaussian processes actually get used in practice? 09:07 What do a kernel's length scale and amplitude actually control? 11:58 What is HSGP and how does it combine with hierarchical models?14:51 Where does PTGP fit in a modern data science workflow? 21:01 Are Gaussian processes interpretable, or are they a black box?27:49 Why aren't Gaussian processes used everywhere already? 32:44 What does a kernel function actually tell you about your data?46:33 What is PyTensor and what does it give you over other backends?50:54 How do you build a Gaussian process model in PyTensor? 52:09 Why is fitting a Gaussian process so computationally expensive?56:00 How does PyTensor's rewrite system speed up GP math for you?59:54 How did an eight-line rewrite replace a matrix inverse in PTGP?01:01:10 Which backends can PyTensor compile your Gaussian process to? 01:11:27 What are inducing points and when should you use them?01:22:09 What goes wrong when you fit a VFE approximation, and how do you fix it? 01:23:18 How do you use an AI agent inside a Jupyter notebook?01:36:06 What are PTGP's skill files and which failures do they catch?01:42:20 How do you balance learning something against shipping it with an LLM? 01:44:28 How do you tell a useful LLM answer from a convincing wrong one? 01:48:37 Why does a good-looking AI output create an illusion of learning? Thank you to my Patrons for making this episode possible! Full links from the show here !